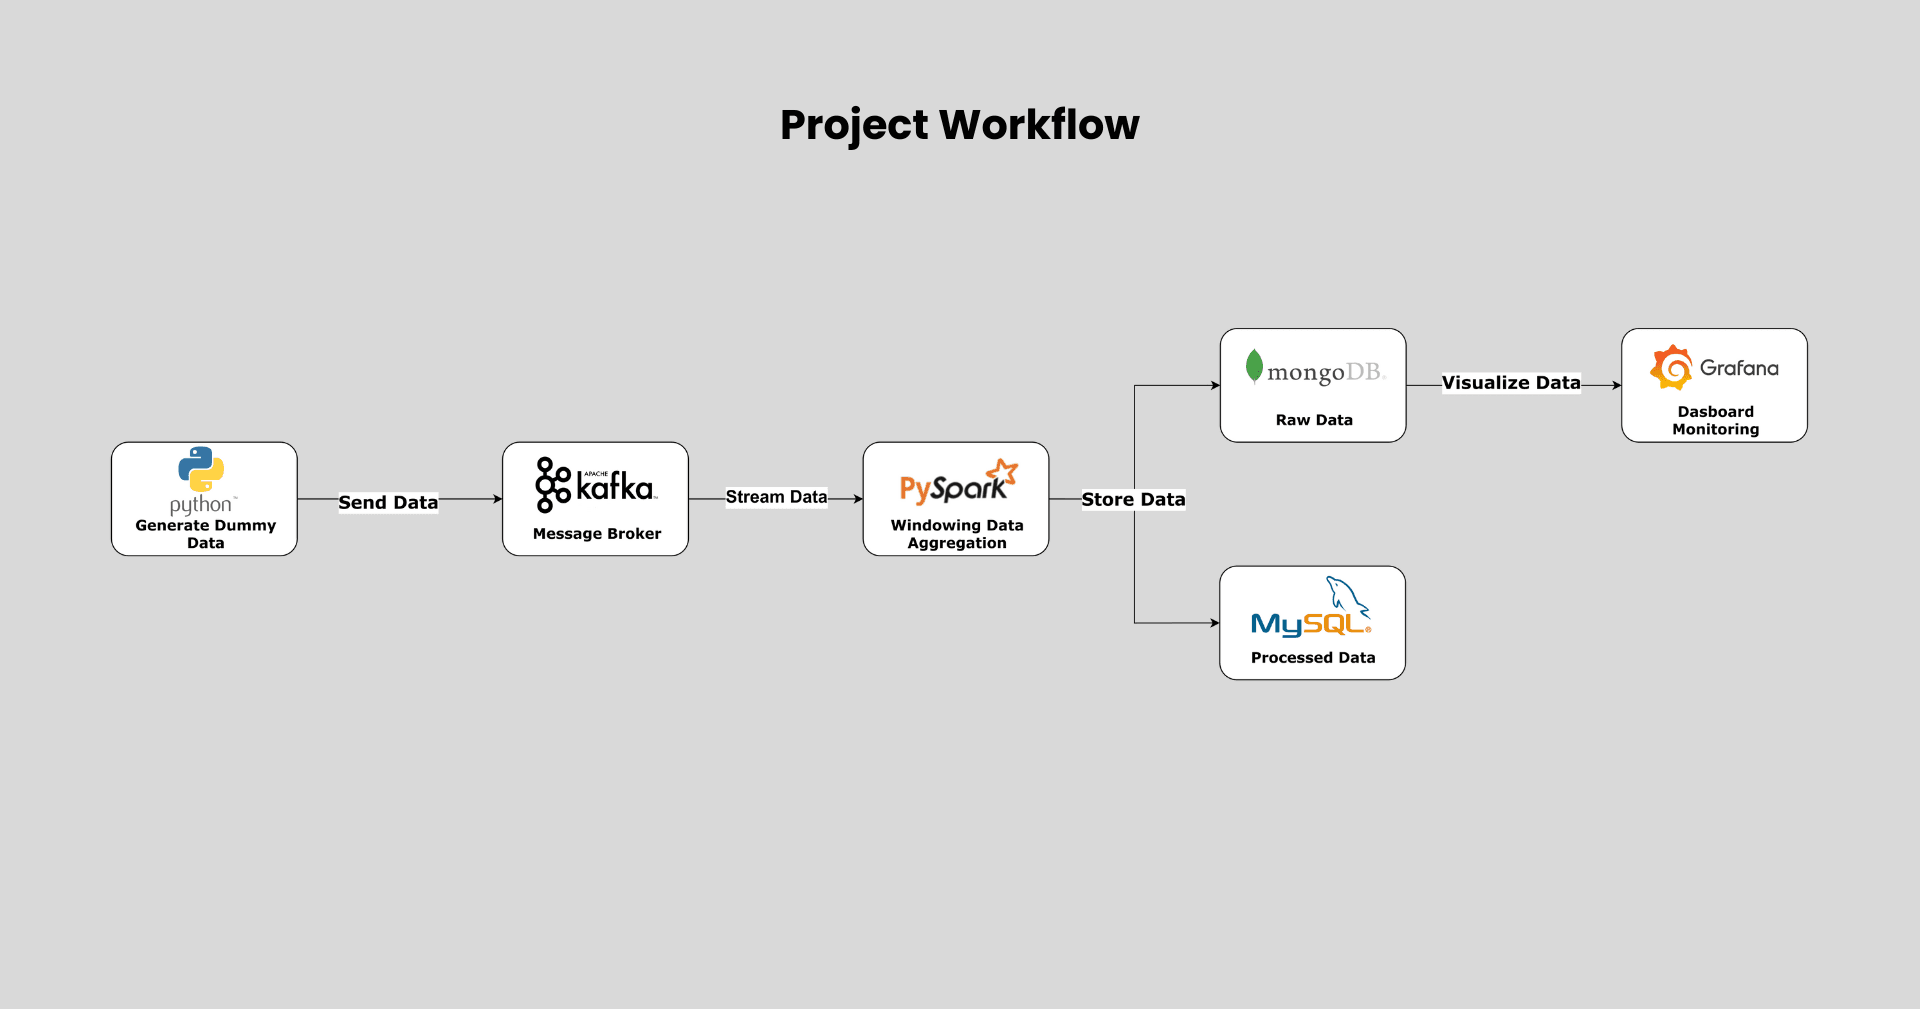
Project Overview
This project showcases an automated data processing pipeline leveraging Apache
Kafka, PySpark, MongoDB, and MySQL technologies with dummy sensor
data for real-time data streaming, processing, storage, and visualization,
demonstrating proficiency in data engineering and stream processing techniques.
The data for this project consists of simulated electrical power consumption
data generated for multiple cities in Indonesia. Each data point includes:
- a timestamp indicating when the data was generated,
- an ID representing the city,
- the name of the city,
- the power consumption in watts (P),
- voltage in volts (V), and
- electric current in amperes (I).
The data is generated in chunks, with each chunk containing information for a
subset of cities. Anomalies are injected randomly with a specified probability,
altering the wattage value to simulate irregularities.
The script continuously produces data and sends it to a Kafka topic named
test_topic using a Kafka producer, effectively emulating a real-time data
streaming scenario.